Skip to content

Mumbai, Maharashtra · 5+ yrs

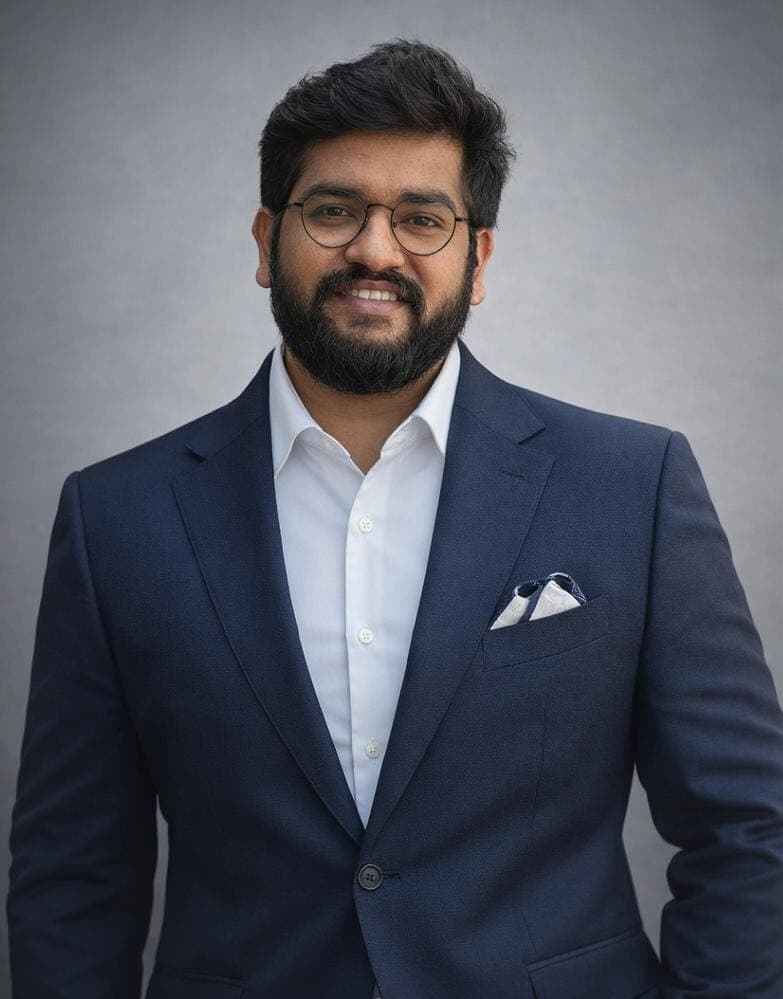
Saurabh PatilData Engineer

Engineering reliable data platforms, from raw data to trusted insights

Building scalable, cost-efficient data ecosystems through intelligent automation, event-driven architectures, and optimized processing, reducing latency while improving reliability and performance.

Saurabh Patil — Data Engineer
SOURCE

About

Hi, I'm Saurabh.

With 5+ years of experience in Data Engineering, I've learned that great data engineering goes beyond moving data from one system to another. It takes thoughtful architecture, reliable ingestion pipelines, data quality checks, CDC implementations, and observability to build platforms that prevent silent failures and deliver trustworthy data.

I enjoy modernizing legacy data systems and transforming traditional, batch-heavy architectures into scalable, event-driven data platforms. For me, a pipeline isn't complete just because the data has arrived, it should be observable, resilient, and designed to handle failures gracefully.

Beyond data engineering, I'm naturally drawn to patterns and repetitive processes that can be simplified through automation. I enjoy exploring system design, understanding distributed systems, optimizing cloud costs, and finding smarter ways to solve engineering problems.

I believe good engineering is about more than making systems work — it's about making them reliable, efficient, maintainable, analytics-ready, and built to scale.

EXPERIENCE

5+ Years in Production

Building production-grade data platforms across engineering, analytics, and BI ecosystems.

PLATFORM MODERNIZATION

Cloud Modernization

Migrating legacy, batch-bound systems into scalable, event-driven cloud architectures.

ENGINEERING APPROACH

Automation & Optimization

Identifying manual bottlenecks and designing smarter, self-healing pipelines that eliminate repetitive work.

PERFORMANCE & RELIABILITY

Built for Observability

Optimizing resource utilization, reducing latency, and implementing robust validation to ensure data teams can trust the output.

STAGED

Technical Skills

Programming & Querying

Languages for data processing, automation, and analytical workloads.

PythonSQLBash / Shell

Data Engineering & Processing

Distributed processing, transformation, and analytical data modeling.

ETL / ELT Pipeline DesignApache SparkPySparkdbt (Models, Tests, Documentation)Data Modeling (Star & Snowflake Schemas)Data Lakehouse & Warehouse ArchitectureStreaming (Apache Kafka)

Data Ingestion & Integration

Batch, incremental, and event-driven data ingestion patterns.

Change Data Capture (CDC)AWS DMSSnowpipeAWS S3 Event NotificationsCSV, JSON & Parquet

Workflow Orchestration

Scheduling, dependency management, and event-driven workflows.

Apache Airflow (DAGs)AWS Step FunctionsAWS EventBridge

Cloud & Data Warehousing

Cloud infrastructure, storage, compute, and analytical platforms.

SnowflakeAWS S3AWS GlueAWS RedshiftAWS AthenaAWS LambdaAWS IAMAWS VPC

Data Quality & Observability

Ensuring data integrity, pipeline health, and production reliability.

Data Quality & Validationdbt TestingAWS CloudWatchLogging & MonitoringError Handling & Alerting

Analytics & BI

Transforming curated datasets into business-ready insights.

Power BIData VisualizationStakeholder Reporting

DevOps & Engineering Tools

Version control, containerization, and automated delivery.

GitGitHubDockerCI/CD PipelinesInfrastructure as Code (IaC)
DEPLOYED

Professional Experience

Software Engineer

Inspiroz IT Services Pvt. Ltd.

Feb 2024 – Present

Navi Mumbai, Maharashtra

Current role
  • Designed and deployed distributed ETL frameworks using PySpark and AWS Glue processing millions of records daily, achieving a 30% reduction in end-to-end pipeline latency across high-volume production workloads.
  • Architected a cloud-native data platform on AWS with Snowpipe-based ingestion, enabling event-driven, near-real-time data availability and improving reliability for downstream BI consumers.
  • Automated Python- and SQL-based reporting workflows, eliminating 10+ hours of manual effort per week and accelerating stakeholder delivery cycles.
  • Led end-to-end migration of SQL Server (RDS) workloads to Snowflake, designing tables, Streams, and Tasks for automated CDC-based transformations.
  • Built modular dbt models with built-in testing as part of the migration, managing the full codebase in Git.
  • Defined IAM role policies, VPC segmentation, and bastion host access controls to enforce data governance, security compliance, and cost governance across cloud resources.
  • Recognized with "Highly Recommended by Client" award for consistent delivery quality — the only engineer on the team to receive this distinction.
PySparkAWS GlueSnowflakeSnowpipePythonSQLdbtIAMVPCGit

Data Processing Analyst

Ipsos Pvt. Ltd.

Jun 2022 – Nov 2023

Thane, Maharashtra

  • Modernized ETL pipelines for monthly, quarterly, and annual tracker studies using Python and SQL, reducing delivery timelines by 15% and cutting manual intervention by an estimated 20+ hours per cycle.
  • Partnered with Data Scientists to translate complex tabulation logic into scalable schemas for BI reporting and ML feature engineering, ensuring analytical consistency across teams.
  • Built and maintained Power BI dashboards for weekly/monthly reporting, enabling operational trend analysis for senior decision-makers.
  • Ingested, cleaned, and transformed large-scale survey datasets from multiple heterogeneous sources, improving data reliability and accelerating analytics turnaround.
PythonSQLPower BIETL

Data Analyst

MSDA LLP

Jul 2021 – May 2022

Mumbai, Maharashtra

  • Implemented scalable web data extraction solutions using Selenium and Requests to collect and structure unstructured data, increasing data availability by 40% for downstream analysis.
  • Refactored and optimized complex SQL queries, improving data retrieval performance and reducing dashboard refresh times by 25%.
  • Developed interactive Power BI dashboards to monitor key performance indicators, enabling data-driven decision-making for senior leadership.
SeleniumPythonSQLPower BI
TRANSFORMED

Featured Projects

Real pipelines I designed and built — problem, solution, and the data flow behind each one.

KIPP Baltimore — Cloud Data Warehouse Modernization

Featured

Problem

Analytical workloads were running on a legacy SQL Server (RDS) database — batch-dependent, difficult to scale elastically, and slow on larger queries as analytical demand grew.

Solution

Migrated the analytical workload to Snowflake with optimized table structures, and replaced batch pipelines with an event-driven ingestion framework built on AWS Lambda, Step Functions, EventBridge, and Snowpipe. Snowflake Streams and Tasks automate incremental data capture (CDC) and scheduled transformations, and the transformation layer is a set of modular, tested dbt models version-controlled in Git.

Pipeline

SQL Server (RDS)
Lambda / Step Functions / EventBridge
Snowpipe Ingestion
Snowflake RAW
Streams & Tasks (CDC)
dbt Staging → Marts
BI / Analytics
CDC (Change Data Capture)Incremental loadingEvent-driven orchestrationdbt modeling & testingData governance (IAM / VPC)Monitoring
Project detailsRepository link coming soon

DPPS — Scalable Data Processing Platform

Featured

Problem

Structured and semi-structured data arriving from REST APIs and relational databases needed to be processed at high throughput, with a full pipeline lifecycle that could be trusted to fail safely and alert when something broke.

Solution

Engineered a distributed ETL system on PySpark and Apache Airflow, with DAGs covering the full lifecycle — ingestion, transformation, validation, and warehouse loading — plus automated retry and alerting logic, and data quality controls built against defined SLA/SLO reliability targets.

Pipeline

REST APIs / Relational DBs
PySpark Ingestion
Transformation
Validation (Data Quality)
Warehouse Loading
Retry & Alerting
Distributed processingAirflow DAG orchestrationData quality controlsSLA / SLO reliability targetsAutomated retry & alerting
Project detailsRepository link coming soon

Inspiroz Insights — Multi-Institution Data Platform

Problem

Multiple educational institutions had operational data scattered across separate systems, making unified, timely reporting difficult.

Solution

Delivered end-to-end ETL pipelines that consolidate operational data from each institution into centralized SQL databases for unified reporting, using Azure Functions for event-driven ingestion so systems stay synchronized in near real time.

Pipeline

Institution Source Systems
Azure Functions (Event-Driven Ingestion)
Centralized SQL Database
Unified Reporting
Event-driven ingestionData consolidationData integrity & availability
Project detailsRepository link coming soon

Zoho Automation — HR Data Integration Pipeline

Problem

HR teams were manually exporting employee records to CSV every month, which was slow and left room for inconsistent, error-prone payroll data.

Solution

Built a Python-based pipeline that pulls employee records directly via the Zoho REST API, transforms the raw JSON payloads into payroll-ready datasets with Pandas, and validates the output before it reaches payroll processing.

Pipeline

Zoho REST API
Python Extraction
Pandas Transformation
Validation
Payroll-Ready Dataset
API-based extractionJSON transformationData validationProcess automation
Project detailsRepository link coming soon
FOUNDATION

Education

Master of Computer Applications (MCA)

NCRD's Sterling Institute of Management Studies

University of Mumbai

Sep 2018 – Jul 2021

Bachelor of Science in Computer Science (B.Sc.)

The SIA College of Higher Education

University of Mumbai

Sep 2015 – Jul 2018

Academic Records

Marksheet / academic record

View Marksheet
CONNECT

Contact

Let's make data do more.

Good things happen downstream.

Looking to build reliable data platforms, scalable pipelines, and analytics-ready systems that turn complex data into meaningful outcomes.

+91 86520 70500 · Mumbai, Maharashtra, India